极致写实:打破AI感的摄影级画质
A reusable reality-first prompt framework that turns a subject, medium, format, setting, shot, and primary realism focus into one coherent, physically stageable image-generation prompt.
gpt-image-2.5 图像
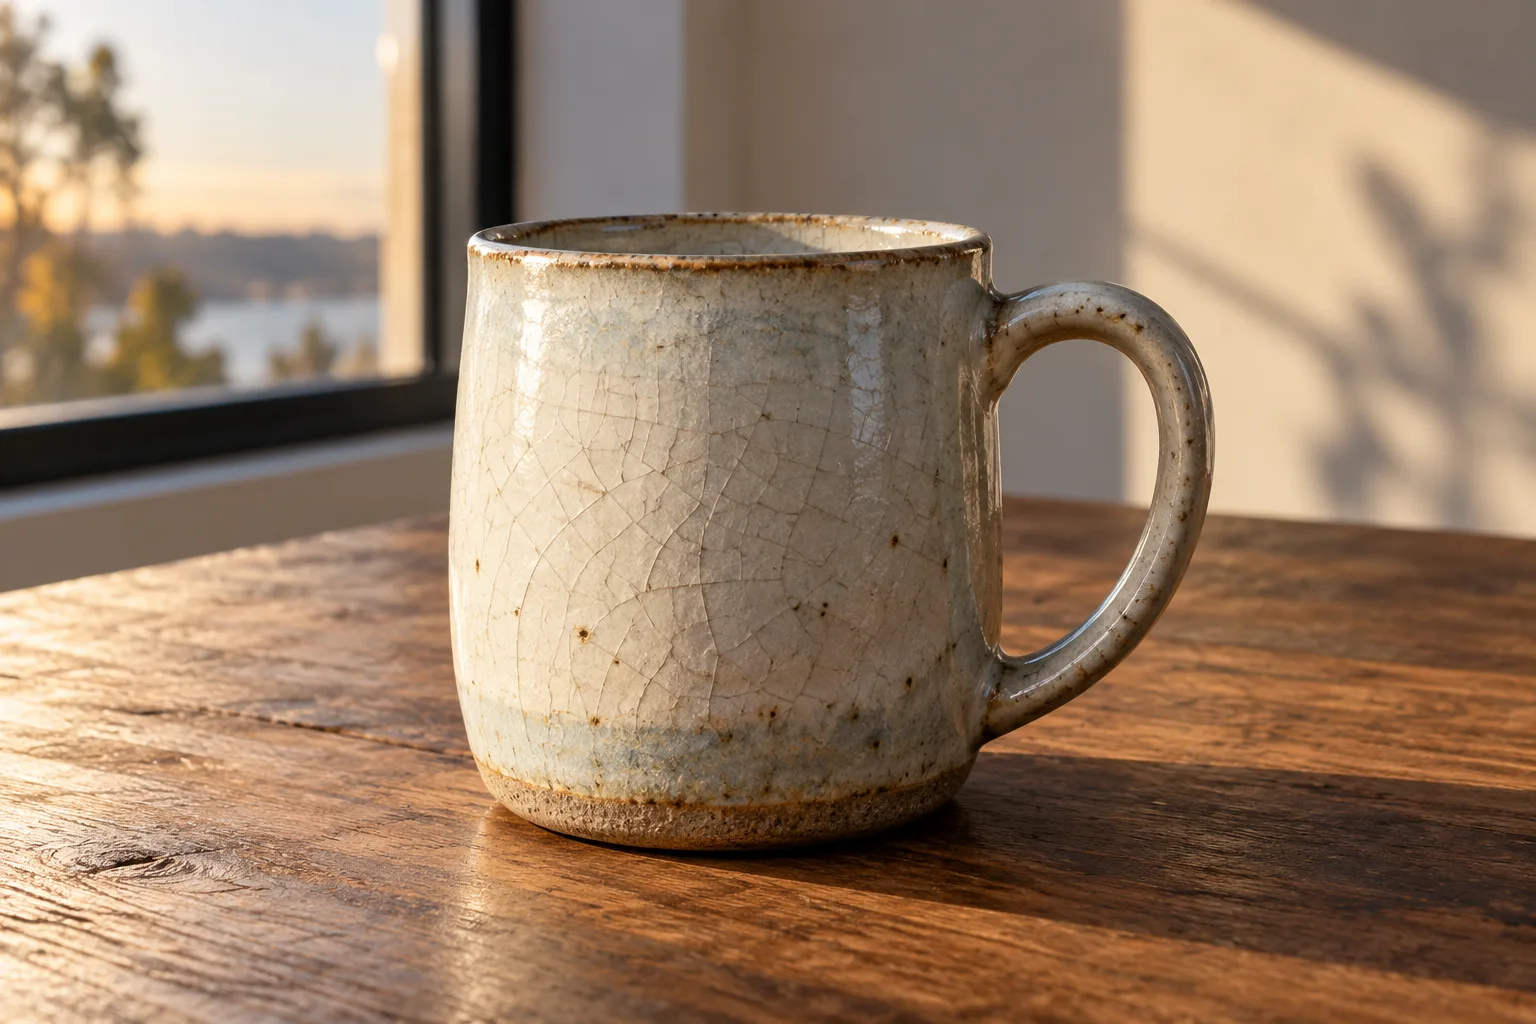
根据以下默认值生成一条连贯的图像生成提示词:主体 = 带有明显釉面开裂纹理的陶瓷马克杯;媒介 = 超写实影棚产品照片;画幅 = 3:2 横幅;场景 = 傍晚大窗户旁的桌面;拍摄 = 距离 50 厘米的四分之三桌面视角,完整呈现马克杯;主要焦点 = 材质真实感。先写硬性约束。使用具体可观察的名词,并用 3-8 个可见细节定义主要焦点。将风格词转化为可实际布置的相机、光线和材质行为。仅在相关时明确白平衡、暖度、对比度、曝光、饱和度、镜头透视、景深衰减、边缘柔和度、颗粒感与运动表现。保持单一连贯的光线和色彩流程,加入针对性的非矛盾负面约束,避免模糊、几何变形、塑料质感、多余物体和泛化的 AI 伪影,禁止虚构文字或标志。最终结果应可信地呈现真实世界,包含微观纹理、自然瑕疵、清晰的主体与背景分离,且不得出现互相矛盾的指令。

【English Prompt】
Create one coherent image-generation prompt from these defaults: subject = a ceramic mug with visible glaze crazing; medium = ultra-realistic studio product photo; aspect ratio = 3:2 horizontal; setting = a tabletop near a large window during late afternoon; shot = three-quarter tabletop view at 50cm distance with the full mug visible; primary focus = material realism. Put hard constraints first. Describe specific observable nouns and 3-8 visible details for the primary focus. Convert style words into physically stageable camera, light, and material behavior. Specify white balance, warmth, contrast, exposure, saturation, lens perspective, depth-of-field falloff, edge softness, grain, and motion behavior only when relevant. Use one consistent lighting and color pipeline, add targeted non-contradictory negatives against blur, warped geometry, plastic surfaces, extra objects, and generic AI artifacts, and avoid invented text or logos. Return a believable real-world result with micro-texture, natural imperfections, clean subject-background separation, and no contradictory instructions.
可直接复制使用 · [方括号] 处按需替换成你的内容
更多提示词
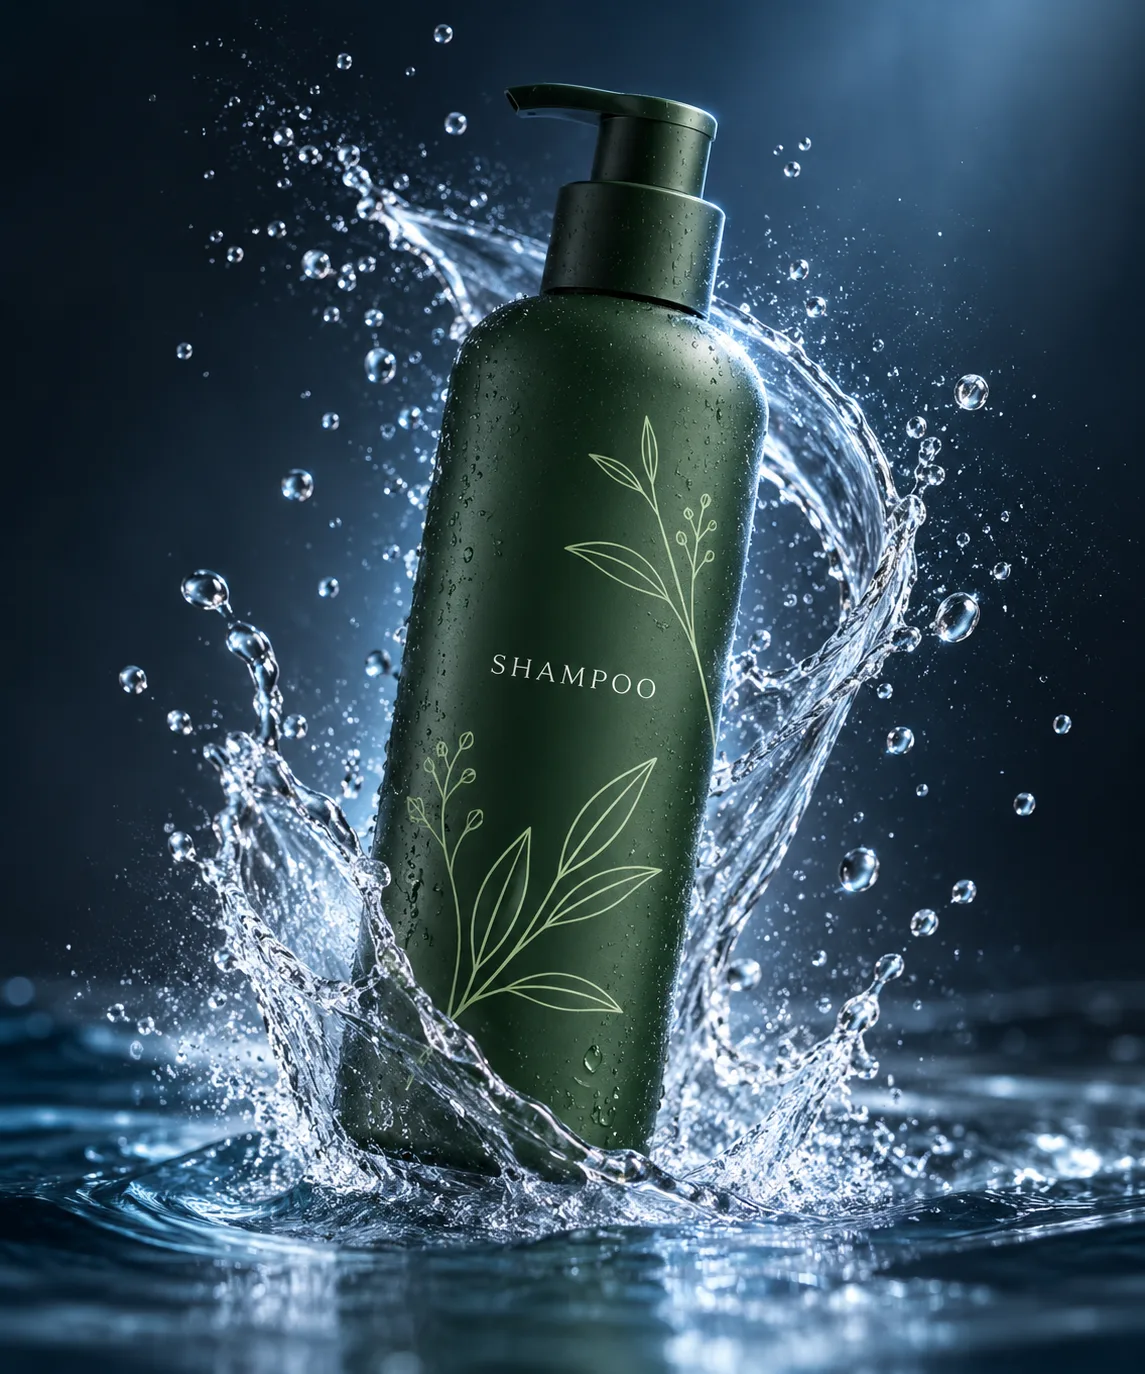
哑光绿瓶的清水飞溅洗发水广告
一只哑光绿色洗发水瓶穿过清澈水花,凝结的水滴与薄雾环绕瓶身;冷蓝影棚光和深色渐变背景营造精致、简洁的个人护理产品广告。 A matte green shampoo bottle moves through a clear-water splash, surrounded by suspended droplets and fine mist; cool blue studio light and a dark gradient create a polished, minimal personal-care product advertisement.
gpt-image-2.5 图像
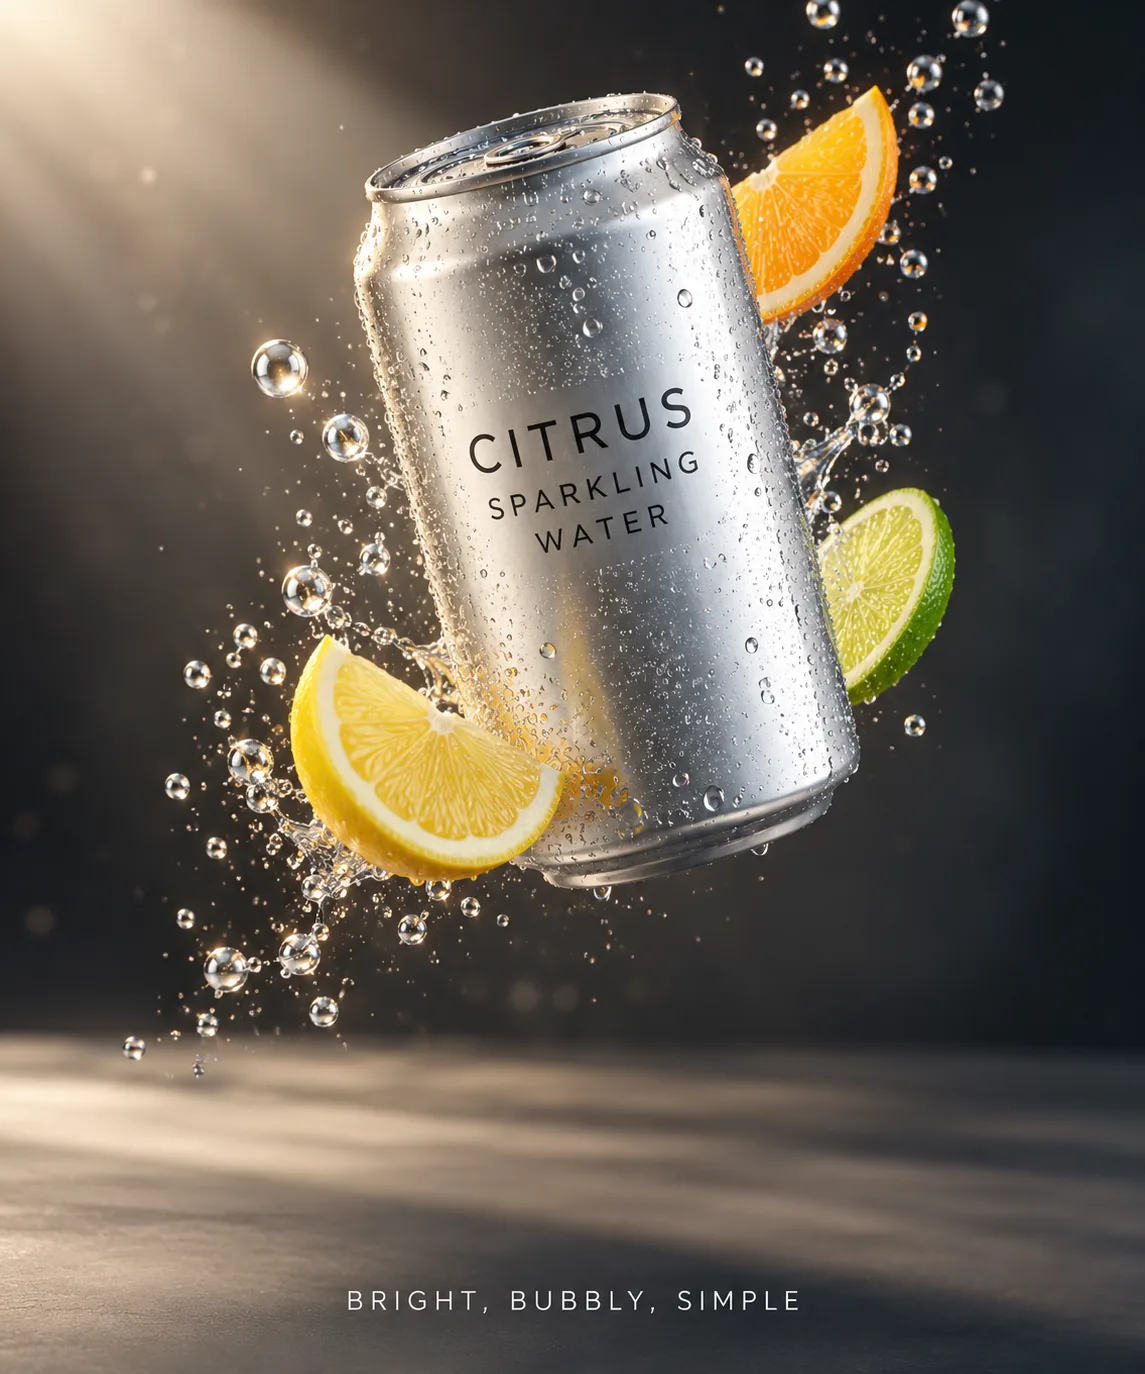
柑橘气泡水的动感3D广告
一罐无品牌柑橘气泡水悬浮在充满动势的影棚场景中,水滴与柑橘片形成克制的粒子轨迹,戏剧性灯光和强对比塑造精致商业广告质感。 An unbranded can of citrus sparkling water floats in a dynamic studio scene, with restrained trails of droplets and citrus slices; dramatic lighting and contrast create a polished commercial-advertising feel.
gpt-image-2.5 图像
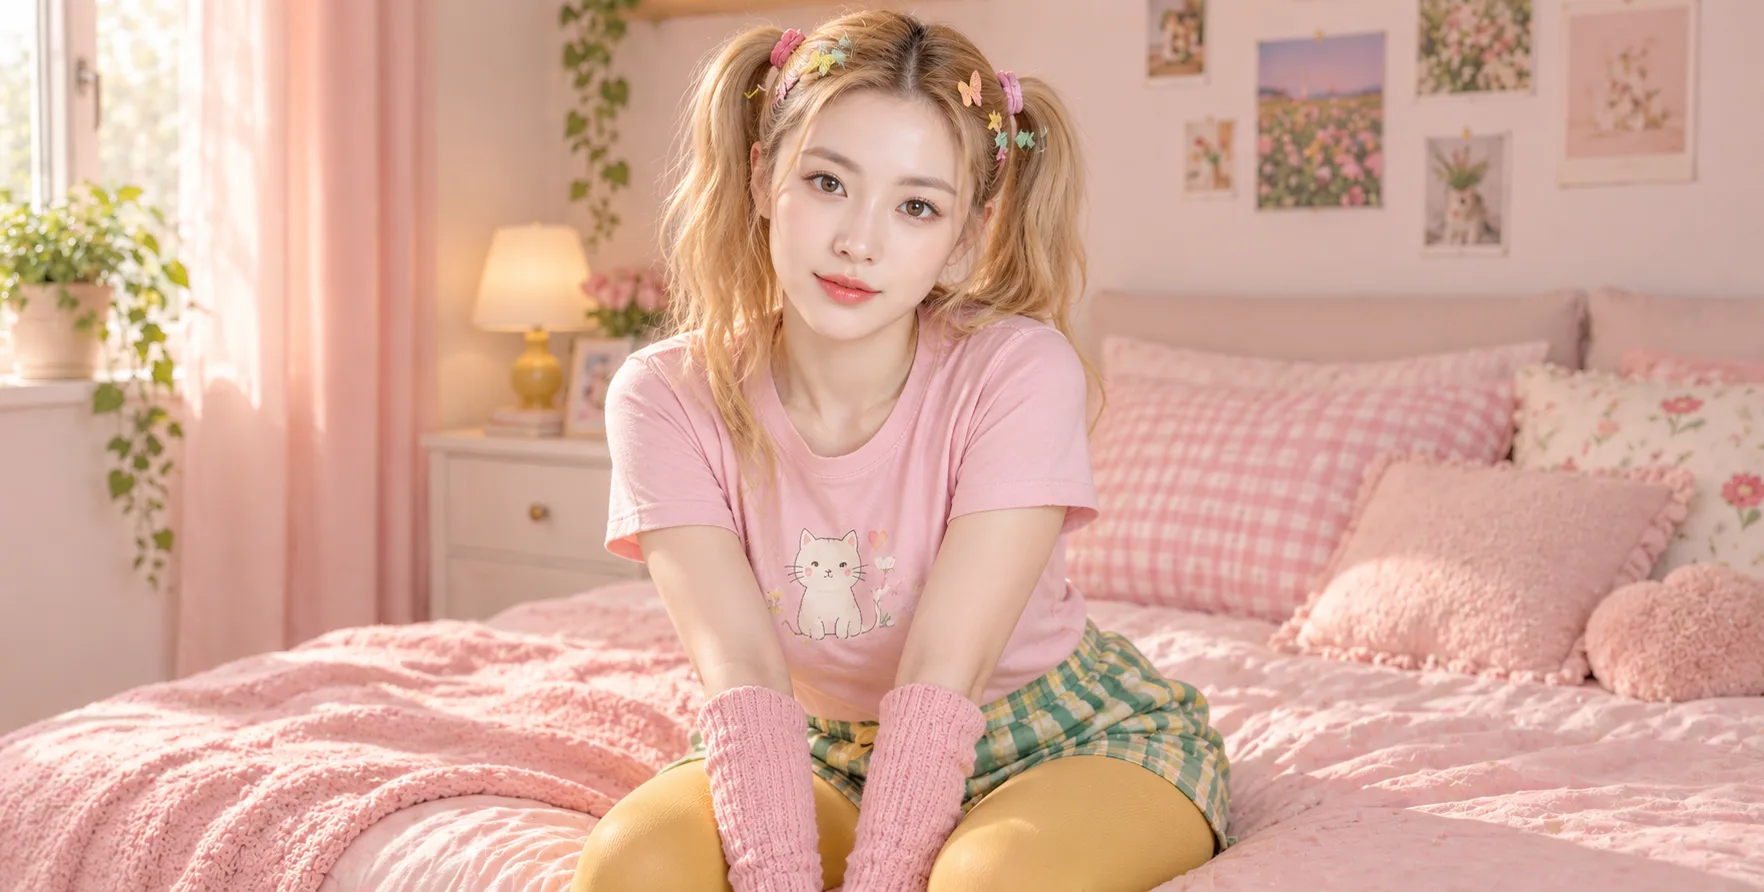
粉彩猫咪主题卧室成人时尚肖像
一位明确成年的时尚女性坐在粉彩卧室的床沿,穿着原创猫咪图案上衣、格纹短裤与保守不透明的打底裤,搭配俏皮发饰。暖和的日光与粉色窗帘营造舒适、轻松的氛围。 A clearly adult fashionable woman sits on the edge of a bed in a pastel bedroom, wearing an original cat-graphic top, plaid shorts, and modest opaque tights with playful hair accessories. Warm daylight and pink curtains create a cozy, relaxed mood.
gpt-image-2.5 图像
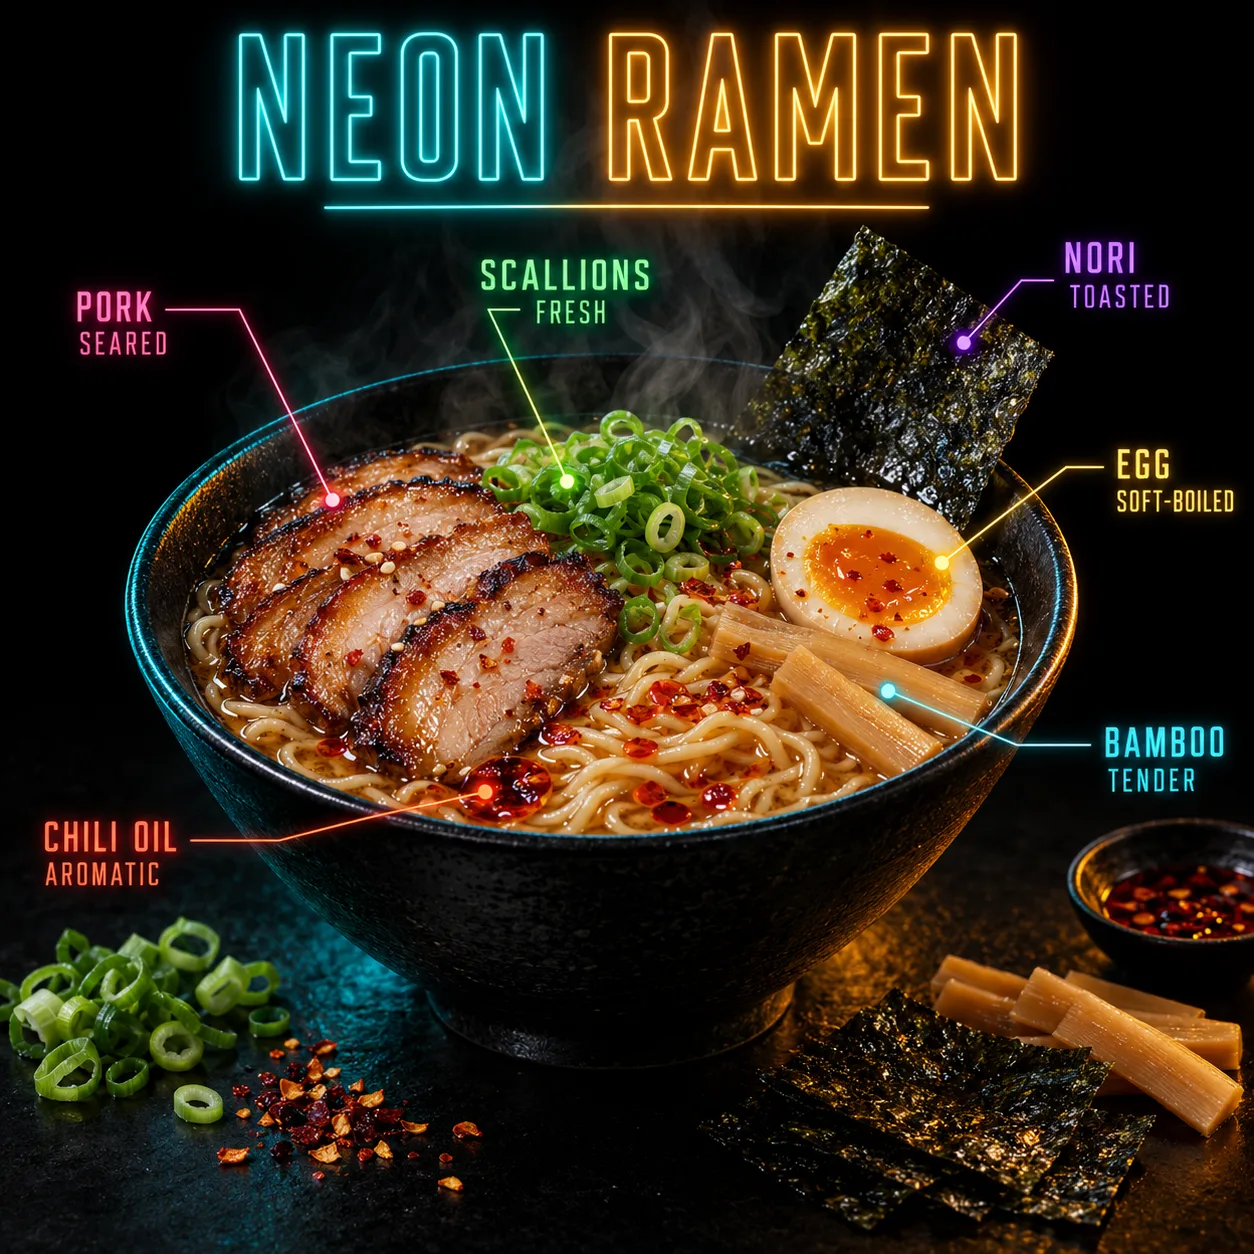
霓虹暗调拉面广告信息图
黑色背景上的戏剧性拉面广告:中央陶碗盛有热气腾腾的拉面,周围点缀少量食材,暖色与电光霓虹边缘光勾勒质感,并以六条清晰引线标签介绍食材。 A dramatic ramen advertisement on black: a central ceramic bowl of steaming noodles, a few supporting ingredients, warm and electric-neon rim light, and six clear leader labels identifying ingredients.
gpt-image-2.5 图像
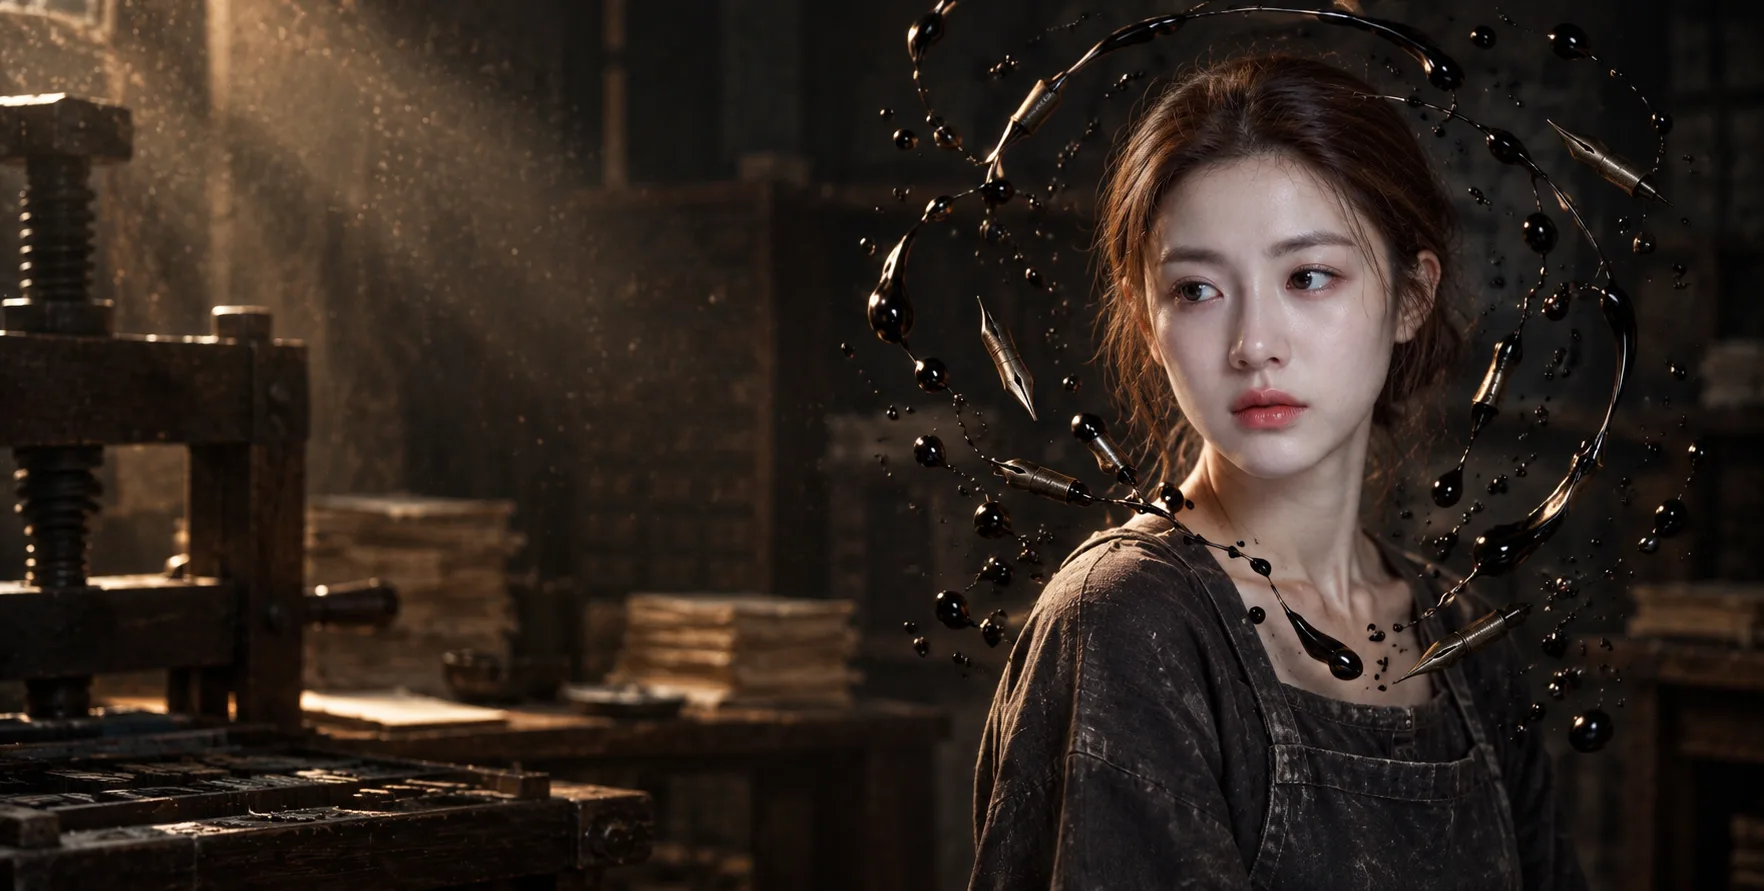
古董印刷作坊中的墨色超现实忧郁肖像
一位成年女性在昏暗多尘的古董凸版印刷作坊中沉思,位于宽幅画面的最右侧,左侧留有大片负空间。抽象黑墨水珠与古董金属字模笔尖在她周围形成密集而有机的悬浮轨迹,但不接触皮肤;暖色光束穿过尘埃,照亮墨水光泽与亚麻工作罩衫。 An adult woman sits pensively in a dim, dusty antique letterpress workshop, positioned at the far right of a wide frame with generous negative space on the left. Abstract black-ink droplets and antique metal nibs form a dense organic suspended pattern around her without touching her skin; a warm shaft of light through dust reveals glossy ink and a linen work smock.
gpt-image-2.5 图像
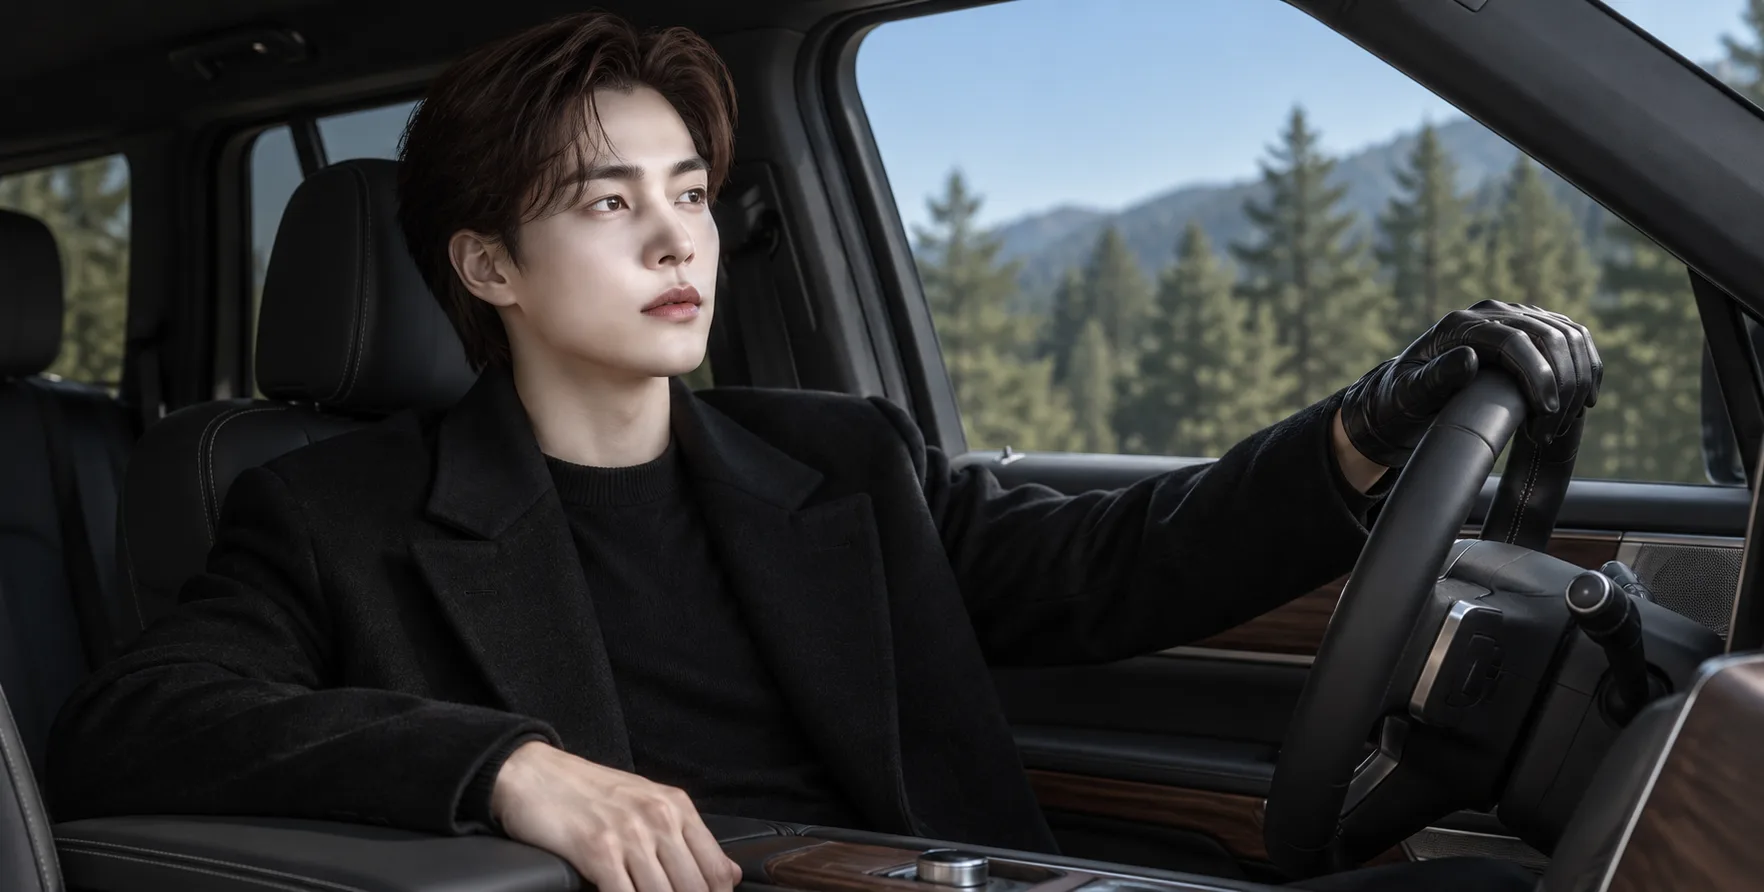
豪华风格SUV内的成年绅士编辑人像
一位成年男性身穿黑色大衣与皮手套,安静地坐在停放中的高端SUV驾驶座,左手轻搭方向盘,目光自信地望向窗外上方。柔和窗光照亮面部,松绿色景观与天蓝色天空映入车窗,黑色内饰和暖棕木饰条营造克制奢华感。 An adult man in a black coat and leather gloves sits calmly in the driver's seat of a parked premium SUV, one hand resting lightly on the wheel and his confident gaze directed upward out the window. Soft window light illuminates his face; pine-green scenery and blue sky appear outside, with understated dark upholstery and warm wood trim.
gpt-image-2.5 图像